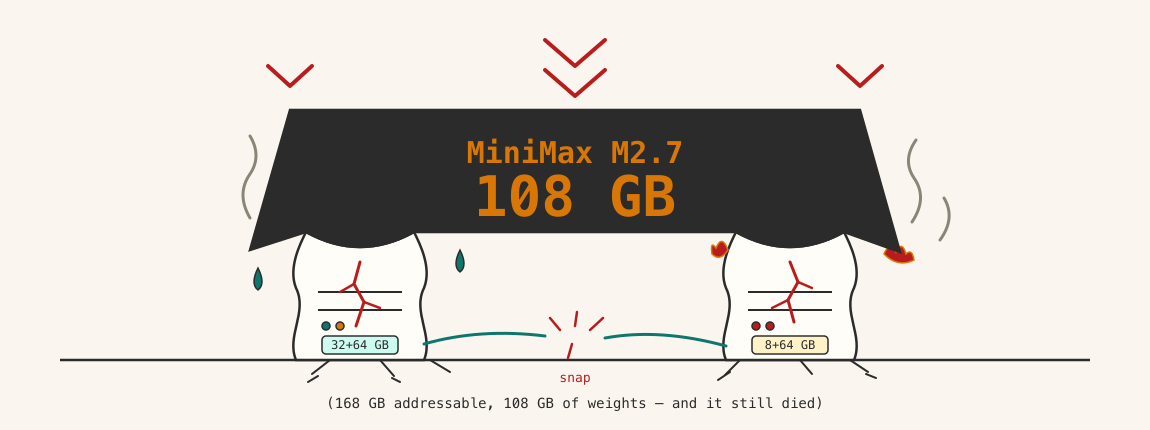
My AI Teaching Setup, Part 4: The 108-Gigabyte Gamble
Parts two and three of this series were about the tidy part: the fleet, the resident model, and the knowledge base working the way the architecture diagrams promised. This is the part where I try something ambitious on a Saturday and spend the day watching my own assumptions lose an argument with physics. In a build log, the experiments that fail are usually the ones worth keeping.
What already worked
Before the gamble, it helps to remember what the fleet was already doing without breaking a sweat. Part 3
covered Strata in detail — the Qwen-Next-style MoE living on hyperion and answering at about 250 tokens per second, vision included — so here is the short version of why it runs that fast.